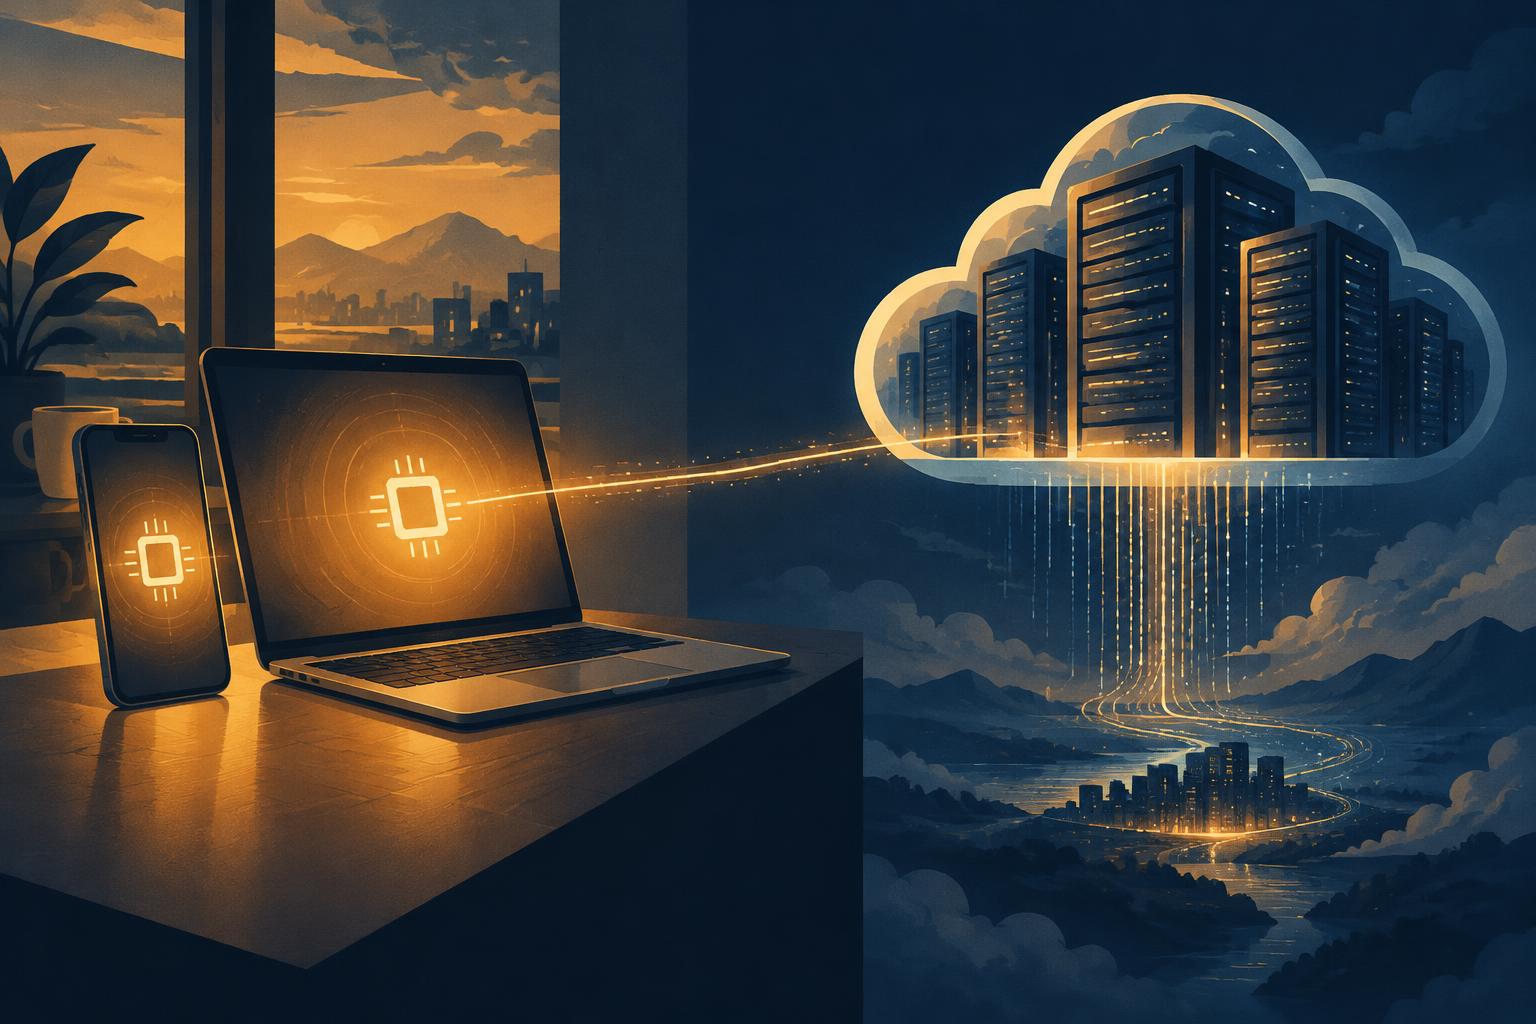
Every AI feature on a modern phone or laptop runs somewhere. Either the model — the file of numbers that does the thinking — sits on the device itself, or your request travels to a data center, gets processed there, and travels back. That single choice explains most of what people argue about in consumer AI: privacy, speed, cost, reliability, and why a feature works on one device and not another.
In 2026 the industry has settled into a split. Small models, typically a few billion parameters, run locally on neural processors built into phone and laptop chips. Large models, hundreds of times bigger, run in data centers and power the chatbots and agents people use for research, coding and writing. This explainer compares the two approaches on the things buyers and everyday users actually feel: privacy and data security, speed, operating cost, and what each means for smartphones, laptops and the new wave of personal AI agents. It draws on the platform companies' own technical documentation and on independent security guidance; it is not a benchmark review.
What runs on the device, and what runs in the cloud
On-device AI means the model's weights are stored on your hardware and the computation happens on its processor, usually a neural processing unit (NPU) designed for exactly this math. Apple's on-device foundation model is roughly 3 billion parameters, compressed to fit in a phone's memory. Google's Gemini Nano runs on supported Android phones through a system service called AICore. Microsoft's Copilot+ PC program defines a class of Windows laptops whose NPUs exceed 40 trillion operations per second, making local AI features a baseline capability rather than an add-on.
Cloud AI is the opposite arrangement: the model is far too large for any consumer device, so it lives in a data center and your request goes to it. ChatGPT, Gemini's largest tiers, Claude, Copilot's cloud features and most AI search products work this way. The largest models are trained and served on clusters of specialized chips, which is why the AI boom's capital spending — covered in our explainer on AI and technology costs — is measured in tens of billions of dollars per company per year.
The important 2026 development is that the boundary is now managed for you. Apple's system decides per request whether the local model is sufficient and routes the rest to what it calls Private Cloud Compute. Android and Windows make similar handoffs. The user experience is one assistant; the plumbing underneath is a relay race.
Apple Machine Learning Research — Apple foundation models 2025 updates
Privacy and data security: the sharpest difference
The privacy case for on-device AI is straightforward. Data that never leaves your phone cannot be intercepted in transit, logged on a server, used to train someone else's model, or exposed in a breach of a service you did not choose. For tasks like summarizing your own messages, transcribing a recording or searching your photos, local processing is a genuine improvement, not a marketing one.
Cloud AI asks for more trust. Your prompt, and often the documents or context you attach, travel to a provider's servers, where they are handled under that provider's retention and training policies. Those policies vary widely between consumer and enterprise tiers, and they change. For sensitive material — health, legal, financial, employer-confidential — the practical rule is to check the specific product's data terms rather than assume.
Two caveats keep the comparison honest. First, hybrid systems send some requests out even when they advertise on-device processing, and the routing decision is usually invisible. Apple's Private Cloud Compute is the most documented attempt to close that gap: the company says its servers run on custom hardware, retain nothing, and publish their software images for outside researchers to inspect. That is a stronger design than a typical cloud service, but it is still a cloud service, and users depend on the implementation matching the description. Second, local processing creates a local target. Microsoft's Recall feature, which indexes snapshots of everything on screen, was delayed in 2024 after researchers criticized how the data was stored; the redesigned version is opt-in, encrypted and gated behind Windows Hello. A database of your activity on your own device is only as safe as the protections around it.
Apple Security Research — Private Cloud Compute
Microsoft — Update on Recall security and privacy architecture (Sept 27, 2024)
Speed: two different kinds of fast
On-device AI is fast in the way that matters for small, frequent tasks. There is no network round trip, so rewriting a sentence, summarizing a notification or suggesting a reply can feel instant, and it works with no connection at all — on a plane, in a rural dead zone, in a concrete building. Google's developer documentation for Gemini Nano lists offline availability and on-device data handling as core reasons to use it.
Cloud AI is fast in a different sense: it can throw enormous computing power at a single hard request. A long research question, a multi-document analysis or a complex coding task would take a small local model minutes and produce a weaker answer; a large cloud model returns a better answer in seconds. The trade is latency and dependence: a slow or absent connection degrades or disables the feature entirely.
Battery and heat sit on the on-device side of the ledger. Sustained local AI work drains power, and devices manage it by limiting how long heavy tasks run. Occasional summaries are unnoticeable; continuous transcription or long agent sessions are not.
Operating costs: who pays, and how
Cloud AI has a meter running. Every request consumes computing time in a data center, and the cost is real enough that it shapes product design: free tiers with usage caps, paid subscriptions of roughly $20 a month for higher limits, and per-token pricing for developers. The falling cost of inference has widened what free tiers offer, but the cost never reaches zero, which is why cloud features are rationed.
On-device AI shifts the cost from a subscription to the purchase price. The NPU, extra memory and supporting silicon are baked into the device, and once you own it, running the local model is effectively free at the margin — no per-request fee, no usage cap, no account required. This is one reason the current memory shortage matters: models must fit in RAM, so AI-capable devices ship with more of it, and that cost reaches buyers, as our PC-prices explainer covers.
For platform companies, the economics cut both ways. Running AI on the user's device costs them nothing per request but sells hardware; running it in the cloud builds a service business but bills them for every query. The hybrid approach is partly an engineering decision and partly an accounting one.
DailyTech — PC prices and memory shortages explained
DailyTech — How the AI boom is affecting technology costs and financial markets
Capability: the cloud's real advantage
Small local models are good at language tasks: summarizing, rewriting, classifying, extracting, short replies. They are not good at knowing things. A 3-billion-parameter model cannot store reliable knowledge about current events, specialized topics or obscure facts, and it will sometimes produce confident, wrong answers — the same failure as large models, more often. Apple paused AI notification summaries for news apps in early 2025 after they misstated headlines, a useful reminder that even routine summarization can misfire.
Large cloud models hold far more knowledge, reason over longer documents, use tools, and can search the live web. Anything that depends on being current, thorough or correct about the world — research, planning, coding help, medical or legal questions — is cloud work in 2026, and honestly marketed products route it there.
The capability gap is narrowing at the low end, not closing. Each generation of phone chips runs a slightly larger or better-compressed model, and techniques like quantization keep improving what fits in a few gigabytes of memory. But the frontier models improve too, and the gap between what fits on a phone and what fits in a data center remains enormous.
Smartphones: where on-device AI is most real
Phones are the strongest case for local AI because the data that makes an assistant useful — messages, photos, location, calls, calendar — already lives there, and because phones are the devices most often without a good connection. Apple Intelligence's writing tools and notification summaries, and Android's Gemini Nano features such as on-device scam detection in calls and messages, are designed around that reality.
The limits are hardware. These features generally require recent, higher-end phones: newer iPhones for Apple Intelligence, specific Android models for Gemini Nano. Older and budget devices get the cloud version, a reduced version, or nothing. Before buying a phone for its AI features, check the manufacturer's current support list rather than the advertising.
Laptops: the NPU becomes standard equipment
On laptops, the dividing line is Microsoft's Copilot+ specification: an NPU above 40 trillion operations per second, plus memory and storage minimums. Machines that meet it run Windows' local AI features — live captions, image tools, the redesigned Recall — on-device. Machines that do not still get the cloud versions of Copilot, which is most of what people actually use.
Apple's Macs have carried neural engines for years and run Apple Intelligence's local features across recent models. The practical picture in 2026: a new mid-range or premium laptop will run routine AI tasks locally as a matter of course, while anything ambitious — a long document analysis, a coding agent, deep research — still happens in the cloud. The laptop is becoming a hybrid terminal: powerful enough to handle your private, everyday AI work, dependent on the network for the heavy lifting.
Personal AI agents: the next generation's real test
The industry's stated direction is agents: software that does not just answer but acts — reading your screen, chaining steps across apps, completing tasks on your behalf. Where an agent runs determines what it can safely touch. A local agent can draw on your messages, files and history without uploading them, which is both the main selling point and the main reason to be careful about permissions.
The security risk is new and does not care where the model runs. Prompt injection — hidden instructions in an email, web page or document that the model treats as a command — is listed by OWASP as the top risk for applications built on large language models, and NIST's generative-AI risk profile treats it as a distinct concern. An agent that can read content and take actions can be manipulated through the content it reads, whether it runs on your phone or in a data center. The defenses are product-side — confirmation before sensitive actions, granular permissions, visible logs — and user-side: be slow to let any assistant send messages, make payments or change settings on its own.
The most capable agents in 2026 are cloud-based, because multi-step reasoning and tool use are exactly what large models do better. Expect agents to remain hybrid for years: a local layer that knows your context and handles routine steps, calling on cloud models for the hard reasoning — with all the privacy and cost trade-offs that implies.
Side by side: a practical comparison
Privacy: on-device wins by default, because data does not leave your hardware; cloud depends on the provider's policies, with designs like Private Cloud Compute narrowing but not eliminating the gap.
Speed: on-device wins for short, frequent tasks and works offline; cloud wins for long, hard requests and fails without a connection.
Cost: on-device is paid once, inside the device price, with no per-use fee; cloud is metered through subscriptions, caps or per-token pricing.
Capability: cloud wins decisively on knowledge, reasoning, currency and tool use; on-device is limited to language tasks on local content.
Availability: on-device requires recent, higher-end hardware; cloud works on almost anything with a browser, which is why the two will coexist rather than one replacing the other.
Which one shapes the next generation?
The honest answer is that the question has already been resolved into a division of labor. On-device AI is becoming the default for private, routine, latency-sensitive work — the layer that makes a personal device feel personal. Cloud AI remains the default for capability — the layer that makes the same device feel smart about the world. Neither is a transitional phase; both are getting better on their own curves.
What will actually shape the next generation of personal computing is the seam between them: how visibly systems show which requests stayed local, how granular agent permissions become, and whether independent researchers can verify privacy claims instead of trusting them. Buyers should watch those three things more than any single model announcement.
DailyTech — AI tools for everyday Americans
DailyTech — Artificial intelligence search engines explained
What this explainer can and cannot establish
This article compares the two approaches using the platform companies' published technical and privacy documentation and independent security guidance. We did not benchmark devices, measure model accuracy, or audit any company's privacy claims. Model sizes, features and routing behavior change with software updates, and availability varies by device and country, so check current documentation before relying on a specific capability.